Layer-Pinned Failure Signals Every Agent Observability Dashboard Must Surface
Dashboards must label every failure to its originating agent layer to enable targeted fixes.
AI agent failure attribution by harness layer means identifying whether a production failure began in the prompt, tool, workflow, memory, or model layer. A useful observability dashboard must attach that label to every failure signal, because the label determines where an engineer can intervene. A signal that reports only that something went wrong is operationally indistinguishable from no signal at all.
Why a green trace can hide a broken agent
Varo Bank’s engineering team found that a change to the vector-database had removed transfer limits from the retrieved context without warning. Faithfulness fell to 65%, and the CI check failed immediately, while every request still returned HTTP 200 within its latency budget. The operational metrics did not change during the regression. The failure was in what the agent knew and said.
Google’s SRE book names four golden signals, which are latency, traffic, errors, and saturation. Those signals describe operational health, but they cannot establish whether an agent’s response was accurate or whether the user accomplished their goal. APM instruments execution. An agent can thus finish every span successfully and still give a wrong, harmful, or useless result.
The gap widens because an agent is a loop. It plans, calls a tool, reads the result, and decides whether to continue, making the full trajectory the relevant unit of analysis. Without a separate detection channel for behavioral failures, teams can learn about them through complaints or manual audits days or weeks later.
The five failure modes that stay invisible to structural traces
Looping occurs when an agent repeatedly calls the same tool without making progress. Slight changes in arguments can disguise the repetition, so exact-match checks alone do not describe the problem. Token totals rise while the dashboard shows throughput.
Tool call failures that return 200 leave the agent reasoning with bad inputs. A search may return nothing, a file read may retrieve the wrong file, or an API may supply a stale value. Transport success does not establish input correctness. Unlike looping, this failure requires inspection of arguments and returned content, because one mechanically successful call can compromise the remaining trajectory.
Tool schema drift has two different faces. A schema mismatch can cause a visible runtime error, while a description mismatch changes when the model selects a tool without producing an error. In a multi-tool system, a small change in user phrasing can also cause the retriever to surface the wrong tool. Selection accuracy measures whether the selected tool fits the user’s intent, even when its arguments pass validation.
Off-task drift develops across an otherwise plausible sequence of steps. The agent begins with the user’s goal but may be solving a different problem by step 12, even though no individual action looks clearly wrong. The trajectory, rather than a span, has diverged. Detecting this failure requires comparing the current working goal with the original intent, which is different from checking for repetition.
Context window overflow and memory staleness deprive the agent of information it needs or supply information that is no longer current. Older content quietly falls out as the context window fills, and long-term memory can return state that is out of date. The symptom may appear several steps after the cause. Diagnosis therefore depends on context utilization and memory provenance, including what the agent read, when it was written, and how it used that information.
These five patterns describe failures whose originating layers may vary. Prompt ambiguity can trigger looping or drift when instructions lack an exit condition, while missing fallback handling can make an agent halt at the first tool error. Missing format specifications create a different downstream problem, in which correct content is unparseable. The symptom alone does not establish the cause. A prompt update and a change to the downstream JSON format can cause failures that come and go days later, so teams need attribution to find the cause.
Why "something went wrong" is operationally useless without a layer label
Harness-Bench establishes that the same model backends can perform substantially differently under different harnesses. System prompts, tools, runtime mechanisms, orchestration, and recovery procedures shape behavior independently of the base model. A poor answer alone does not show that the model has a defect. Without that distinction, a team can change the model while leaving the mechanism that caused the failure untouched.
A prompt lacking an exit condition calls for a different intervention from a tool returning stale data, a workflow unable to resolve a decision, or memory supplying outdated state. No intervention is correct for all five layers. A generic quality alert may establish that an incident exists, but it does not direct repair.
A loop is visible at the workflow layer, yet its root cause may be a prompt that never tells the agent when to stop. The dashboard’s signal label identifies the first inspection point. The attribution process must then establish whether that layer owns the defect or merely exposes its effects.
Multi-agent orchestration makes that distinction harder because the originating span can be two or three agents removed from the observed symptom. A shared trace ID links those agent boundaries so that investigation can follow the failure backward. Otherwise, cause and consequence look like unrelated events. Engineering requires a path from the visible failure to the responsible component.
The layer-pinned signals a production dashboard must surface
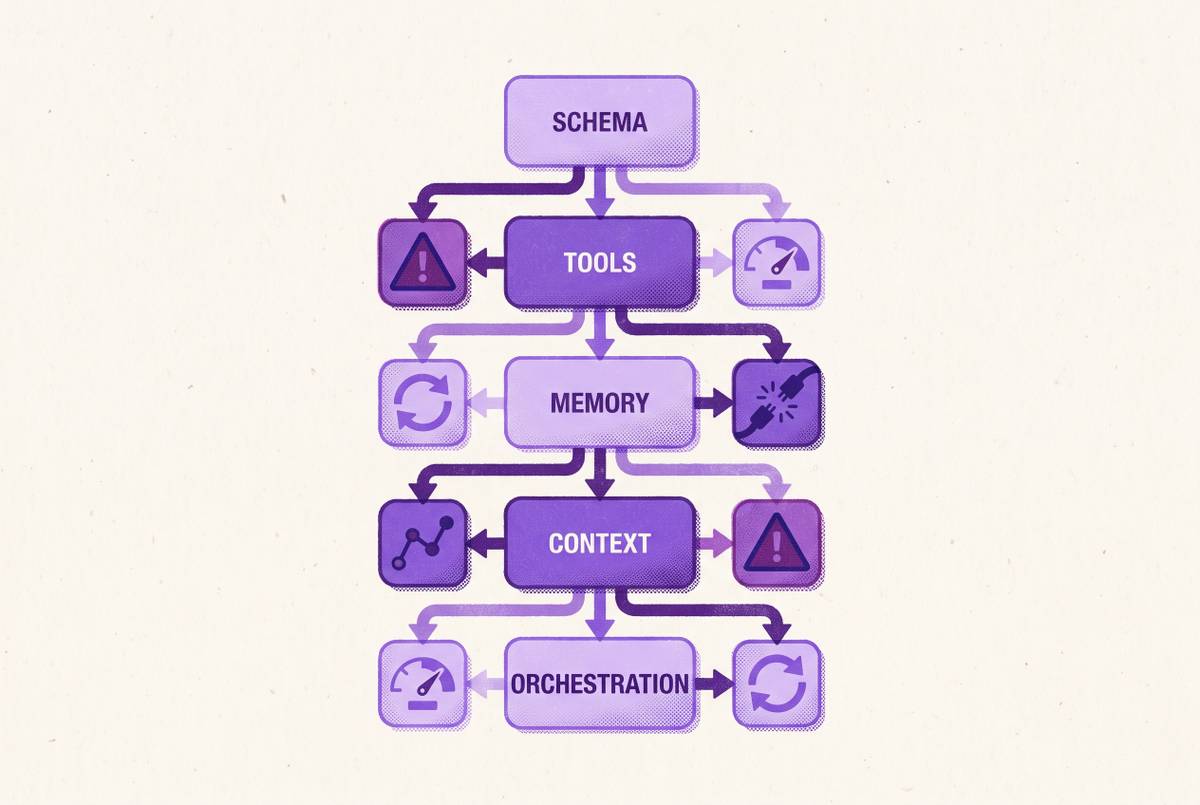
To make that path usable, a production dashboard should tag every failure signal to the prompt, tool, workflow, memory, or model layer. Each label must name a category and point to evidence an engineer can check. The following signal groups define that inspection surface. They distinguish the layer where a warning appears from the root cause that subsequent investigation must establish.
The prompt layer needs prompt version tracking. Every span should include version metadata so that a behavioral shift can be correlated with the system prompt in use. A staging edit otherwise loses its connection to production behavior. Version tracking gives teams evidence to check whether a new failure pattern comes from missing exit conditions, fallback instructions, or format specifications.
Argument validity must establish that the agent supplied valid, non-hallucinated values. A field rename from customer_id to account_id can silently disrupt an agent that passed staging evaluations. HTTP status cannot resolve that mismatch by itself.
Return-quality checks should flag empty results and values that are older than the set freshness threshold. Selection accuracy must separately assess whether the chosen tool was semantically appropriate for the user’s intent, because valid arguments cannot rescue the wrong tool choice. These checks answer distinct diagnostic questions. Together, they distinguish a defective invocation, an unusable result, and description drift that changes tool selection without a runtime error.
Loop detection should spot calls that repeat within a run even when the arguments change a little. Step counts and how close a run is to the maximum step limit show which runs cannot reach a decision or have no exit condition. Neither signal requires an individual span to fail.
Off-task detection requires a per-turn semantic classifier comparing the original intent at turn 1 with the current working goal at turn N. A decline in similarity signals possible divergence. Cross-agent correlation supplies a different kind of evidence. A shared trace ID must connect the originating span to downstream symptoms across agents, so that the component displaying the error is not automatically blamed for causing it.
Each memory span should record what was read, when it was written, and what the agent did with it. That record makes stale-state failures open to inspection. Context utilization should show the percentage consumed at every step, because generic, hallucinated, or instruction-ignoring responses can appear downstream of the moment older content fell out.
The model layer needs version drift, cost per successful task, and guardrail trip rates. Response metadata can reveal a different dated snapshot despite an unchanged alias in code. A rise in cost per successful task can reveal retries and over-prompting even when error rates stay flat, and more safety-filter trips can be a sign that behavior has changed. These signals warrant investigation into possible model fault.
OpenTelemetry’s GenAI semantic conventions provide a vendor-neutral schema for span names, token usage, finish reasons, and agent and tool-call spans. That standardization gives teams a common execution record. It does not classify response quality or failure modes. The layer-pinned detection system must sit above that record and interpret what the trajectory achieved.
How structured attribution turns a pinned signal into a verified fix
AgentDebugX formalizes the transition from detection to repair through a closed debugging loop. Detect identifies step-level errors, Attribute locates root causes across the trace, Recover proposes ranked fixes, and Rerun regenerates the trajectory around the failure point. Each phase has a separate evidentiary role. Detecting a bad output does not establish its origin, and identifying an origin does not prove that a proposed change will resolve it.
The research places DeepDebug at the core of multi-turn root-cause diagnosis. It combines global trajectory understanding, structure-guided investigation, and cross-examination to produce an auditable report with the responsible agent and step, supporting evidence, an explanation, and one concrete fix. The report makes the diagnosis open to review. Its value lies in connecting the proposed intervention to the trace rather than presenting a plausible explanation without support.
For production teams, that process requires converting a failed production trajectory into a test case in the evaluation suite. An evaluation harness can then define golden tasks, replay tool calls deterministically, score runs against rubrics, and block regressions in CI. Production evidence keeps the test suite relevant. Without that link, deployment checks can remain centered on synthetic happy paths while real failures recur outside them.
Replay validation establishes whether the proposed repair survives known cases. Varo Bank’s groundedness check ran the same 200 prompts on every build and on a schedule against the live model, catching a regression before users saw it. The same discipline applies to prompt edits, tool schema updates, and workflow restructuring. A changed configuration is not yet a verified fix. Historical traces provide the cases against which its effects can be assessed.
The resulting change must also be inspectable. An automatic repair that modifies a prompt or tool schema without explaining why creates a governance problem even when the immediate result improves. Engineers need the layer, span, evidence, and reasoning behind the intervention. The attribution report is therefore part of the repair artifact, preserving an account of what changed and why it was defensible.
Treating layer-attributed failure patterns as an ongoing engineering discipline
Agent behavior can drift as prompts, tools, models, and data change under a fixed codebase. An incident closed after one successful replay does not exhaust the value of its evidence. Failures that keep happening reveal work for the engineering backlog. The same layer taxonomy used on the dashboard should organize that work, keeping prompt defects, tool maintenance, workflow changes, and memory problems attached to their responsible components.
A recurring prompt-layer failure should become a prompt engineering task, while repeated tool schema drift should become tool maintenance work. Neither pattern becomes a model problem merely because an LLM produced the final answer. Attribution helps teams avoid that mistake and work on changes that can fix the cause.
Teams should label spans by layer, run offline evaluations on samples of production traces, and add failure patterns whose causes have been found back to the test suite. The eval set then evolves with actual use. Each deployment can be assessed against failures the system has already encountered, turning observability from a record of past incidents into an engineering input for the next release.