Memory Layer Architecture for Long-Running Production Agents
Three-layer memory architecture prevents semantic drift in long-running production agents.
Memory architecture for long-running agents is the discipline of deciding what an agent remembers, where that memory lives, and how it gets retrieved across sessions, not how big a context window it has. The failures this discipline is built to prevent, semantic drift, lost persona consistency, entity confusion, and factual instability, show up as diagnosable patterns in production traces, and they map to specific, named architectural choices.
Why memory architecture for long-running agents is a distinct engineering problem from context window sizing
Treat the question of how an agent remembers as separate from the question of how much it can read at once. Fofadiya and Tiwari's Multi-Layer Memory Framework paper frames the real research problem as long-term context retention under a constrained memory budget: as a dialogue gets longer, earlier signals get compressed or dropped, and the agent starts drifting on entities and facts it should have kept straight. A bigger context window changes the trade-off between accuracy and latency, but it does nothing to fix the governance and drift problem that the constrained memory budget produces. The two axes move independently of each other. A team that assumes a longer window will solve its memory problems is answering a question nobody asked.
The distinction that actually matters here is between memory type and memory architecture. Atlan's architecture survey draws this line clearly: memory type, working, episodic, semantic, procedural, describes what's being stored. Memory architecture is the system design: which storage substrates hold that content, how retrieval pulls it back out, and how the agent's control logic decides what to use and when. If you conflate the two, that's the most common reason production agents fail once they're running at real scale. Teams ask which vector database to use before they've decided what memory architecture the agent needs in the first place, and that ordering problem does not appear in testing. It appears under load, weeks into a deployment, when a user's session five conversation contradicts what the agent told them in session two.
The three-layer model of working, episodic, and semantic memory
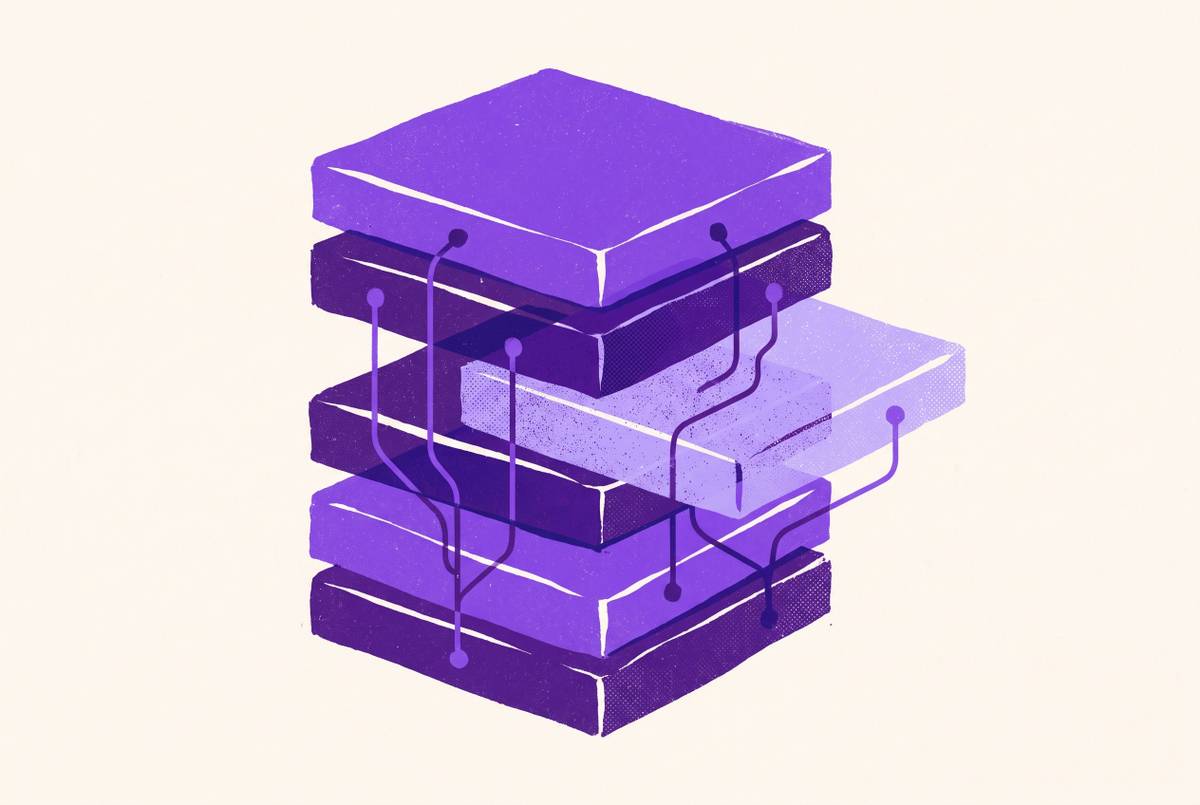
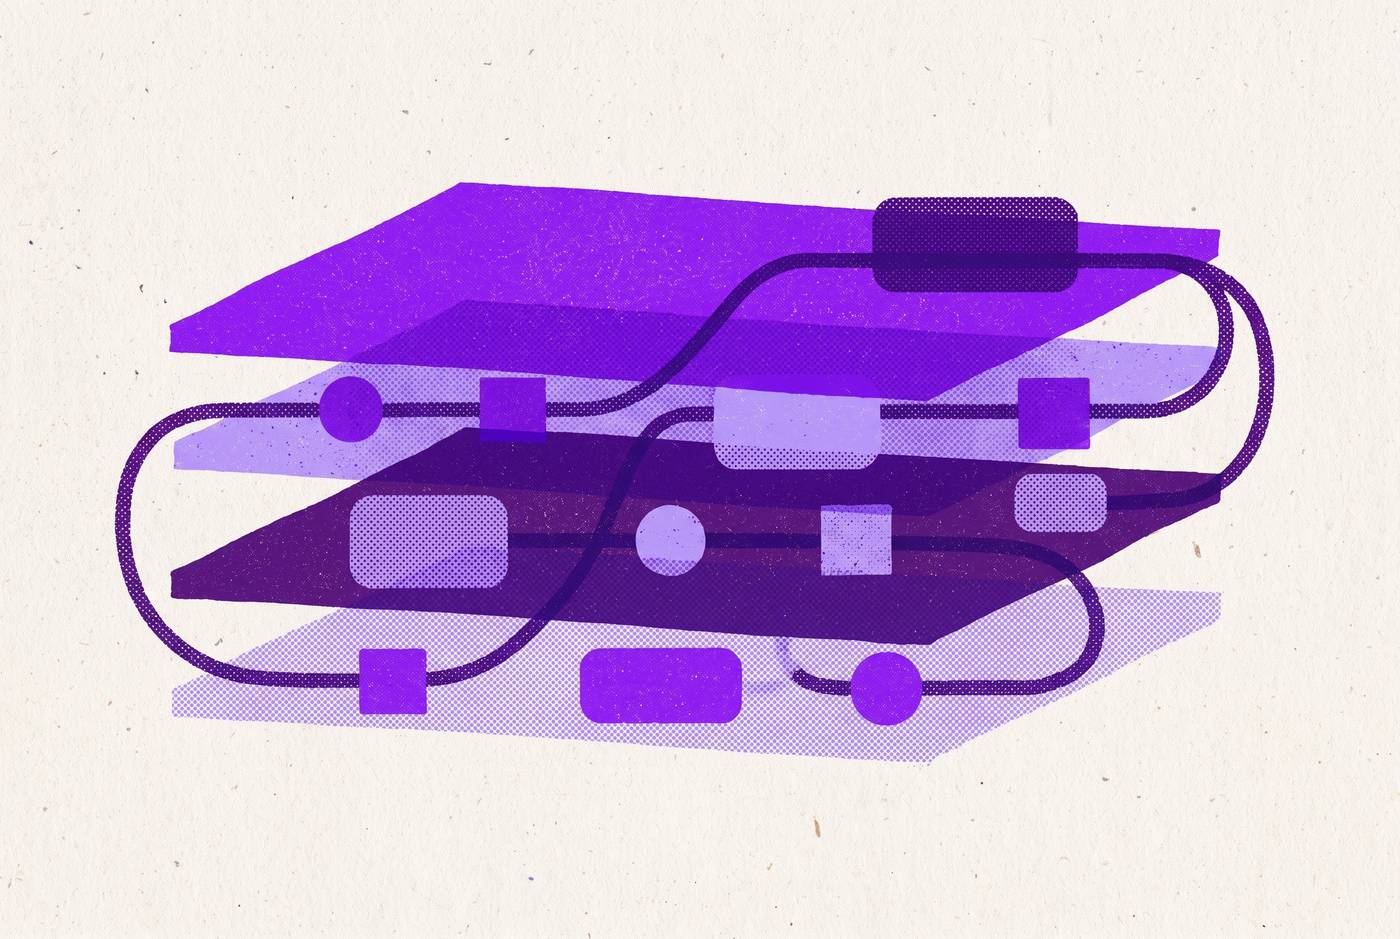
A layered approach to memory is the direct answer to how flat-context systems break down once sessions stretch past a handful of turns. The Multi-Layer Memory Framework splits dialogue history into three layers, and each one has a separate job.
Working memory holds recent interaction inside a bounded window. It's what the agent reads from and writes to in order to finish the turn in front of it, nothing more. Episodic memory accumulates compact summaries of each session, a structured record of what happened, not a raw transcript the agent has to re-parse every time. Semantic memory holds structured, entity-level facts, the stable information about a user or a domain concept that should hold steady across dozens of sessions, not just the one in progress.
None of this works without two additional mechanisms. The framework adds an adaptive layer-weighting system that decides how much retrieval importance each layer gets for a given query, and a retention stability objective that keeps semantic facts from shifting session to session without reason. Strip those out and the three layers stop cooperating. They turn into three separate stores that can quietly contradict one another with no referee to catch it.
The benchmark results back this up. Across LOCOMO, LOCCO, and LoCoMo, the framework held six-period retention above half of all sessions, cut the false memory rate substantially, and used meaningfully less context than full-context baselines. Atlan's own survey of production systems found that most combine two or more of the five architecture patterns it identifies, a finding that lines up with the three-layer framing: real workloads need one retrieval strategy for what just happened, another for what's accumulated over time, and a third for facts that need to be governed and audited. An agent built only on working memory can't carry a user's stated preference into next week's session. One built only on semantic memory can't reason well about what just happened five minutes ago. One that lets episodic and semantic storage blur together accumulates contradictions it has no way to resolve on its own.
The five architecture patterns teams deploy, and the accuracy-latency trade-offs each one makes
Five distinct memory architecture patterns are in use in production systems today, and picking among them is a trade-off across accuracy, latency, token cost, how much relational reasoning the task needs, and how much governance it demands. None of the five is simply "the best one."
Atlan's survey lays these patterns out in order of rising complexity. Pattern 1 puts all memory in the prompt: system instructions, conversation history, and retrieved chunks, all loaded at inference time. When the session ends, the memory ends with it. There's no persistent storage, which makes it the fastest pattern to build and the cheapest to run, right up until conversations start running long. Pattern 2 is a flat external vector store: persistent semantic search over embeddings, with retrieval happening at query time. On the LOCOMO benchmark from 2025, this pattern hit the fastest p95 latency measured, 1.44 seconds, but it struggles with relational and multi-hop reasoning because it has no structure connecting one fact to another. Pattern 3 is hierarchical working memory: subgoal-based chunks with summarized observations replacing raw ones to keep retention selective. It improves efficiency inside a single session, but you build it mainly for intra-session tasks, not for carrying facts across sessions. Pattern 5 is the enterprise context layer: an organization's existing governed metadata graph, repurposed as agent memory, with temporal validity, lineage tracking, and access policy built in. It needs real upfront investment in ontology and governance work, and it pays that back with the highest accuracy and the strongest auditability of any pattern, which is why regulated environments gravitate toward it.
The accuracy-latency trade-off runs right through the middle of this list. In LOCOMO testing, in-process working-only memory hits the highest standalone accuracy of any single pattern, but the flat external vector store hits the lowest latency. That gap is the core pricing decision every team has to make: how much accuracy is worth trading for how much speed, for this specific workload. Token cost matters just as much. Full-context approaches burn through close to an order of magnitude more tokens per conversation than selective retrieval does, so you only get financial sense from the Pattern 1 baseline for short sessions. Past a certain length, the bill forces a different design.
Most production systems end up combining two or more of these patterns. The real question a team has to answer is which combination to run, and at which layer boundary each pattern takes over from the next.
How naive full-context injection and missing retrieval gating produce diagnosable failures in production traces
Most memory failures in production aren't caused by hardware limits or a weak model: they're mismatches between what gets injected into context, what actually gets retrieved, and what the task in front of the agent needs, and they appear in traces in specific, findable ways.
Full-context injection is the clearest case. Pasting the entire conversation history into every single prompt produces memory interference, where earlier signals suppress or contradict later ones, and it produces quadratic growth in context size that makes inference cost unsustainable at scale without buying any improvement in accuracy. The Multi-Layer Memory Framework paper names plain concatenation of dialogue history as the direct cause of memory interference and inefficiency, and its results show context usage dropping substantially once structured layering replaces concatenation, while retention stays the same.
Missing retrieval gating is the second failure mode, and it runs in both directions. Without an adaptive mechanism to weight retrieval by which layer is relevant to a given query, agents either over-retrieve, flooding context with historical material that has nothing to do with the current turn, or under-retrieve, missing facts that live in episodic or semantic memory because the system never looked there. The framework's adaptive layer-weighting mechanism exists specifically to fix this: it decides which layer's content gets priority for a given query type, and it brought the false memory rate down to 5.1%, well below the rates flat retrieval baselines produced.
Both failures leave the same kind of trace signature. A run can look like it succeeded at the final output level, the response reads fine, while the intermediate tool calls and reasoning steps show context that's been corrupted or contradicted somewhere along the way. Standard observability tools, the ones watching HTTP status codes and latency numbers, will not catch this. These structural failures, semantic drift, entity inconsistency, factual instability across sessions, are exactly the kind of pattern that only becomes visible once someone is looking at the trace itself. Platforms like Moda that attribute a multi-turn failure to a specific memory layer, working, episodic, or semantic, rather than filing it under a generic "the agent got confused," are what makes the line between a context-window problem and an architecture problem visible in real deployment data. Teams need visibility into what was actually read from memory at each step, not just whether the final answer came out right. Otherwise the failure stays invisible until a user complains about it.
Cross-session semantic drift as a distinct failure category with its own trace signature
Semantic drift is the hardest memory failure to catch because it builds up quietly across sessions. It happens when an agent's stable facts about a person or entity shift gradually, start contradicting what an earlier session recorded, or simply go stale, and catching it requires comparing memory state across session boundaries.
The Multi-Layer Memory Framework paper treats drift as a research problem in its own right. Its retention regularization objective is built specifically to constrain how much semantic memory is allowed to shift from one session to the next, and its six-period retention metric, 56.90% in testing, exists to measure whether semantic memory holds steady across an extended run of sessions. Take that mechanism away, and agents storing user facts in semantic memory build up contradictions over time: a user corrects a fact or updates a preference in session four, the representation from session one never gets updated to match, and a later retrieval query that happens to pull from session one material comes back with the outdated version, with nothing flagging that it's stale.
The trace signature here looks different from a tool failure or a bad prompt. Across several sessions, the agent's stated understanding of an entity changes with no explicit correction from the user in the current conversation. The actual cause is a semantic memory write from some earlier session, not the current prompt and not the current tool call. That's what makes drift harder to track down than most failures: the broken piece of evidence can sit much earlier in time than the output it eventually corrupts, buried in a previous session's trace, which turns root-cause attribution into a search problem across a distributed log. The root-cause attribution research on this point is specific: execution logs can run to millions of tokens, and the evidence needed to explain a failure can be sparse, can appear long before the final outcome, and can sit scattered across distant parts of the log, which is why attribution ends up being a search problem. That same research flags a related risk, that language models tend to settle on whatever failure looks plausible before they've actually searched the rest of the evidence.
Confirming that a three-layer design actually cuts down on drift and contradiction in a live system means replaying real agent traces against the new architecture, not just trusting a benchmark number. The question is whether layer-weighting and retention regularization hold up against the specific failure patterns a given deployed system runs into. Trace-driven validation tools let a team check whether the three-layer split gets rid of the contradictions a flat approach would have let through, measured against their own workload.
How the memory layer interacts with tool schema drift and prompt ambiguity to produce compounding failures
A memory failure rarely stays contained to the memory layer. Stale or badly retrieved facts flow straight into tool calls and prompt templates, and what started as a memory design flaw ends up getting logged as a tool failure or a reasoning error, attributed to the wrong layer.
Tool schema drift is one clear path this takes. When an agent pulls a cached tool schema out of semantic memory and the real tool API has since changed, the tool call gets built against a schema that no longer matches reality. A malformed tool call appears in the trace, but the actual cause is how the memory layer represented that schema, not the tool's own definition.
Prompt ambiguity is the second path. When episodic memory injects a session summary that's vague or under-specified, the prompt inherits that vagueness directly. A prompt already working to tell apart two similar user intents gets harder to disambiguate the moment the injected memory adds a contradictory frame on top of it. Retrieval over stale semantic memory produces its own version of this problem: the agent builds a response around facts that were true in some earlier session but no longer hold, and the prompt has no built-in way to flag that the information is stale. From the outside, that looks like a hallucination. It's actually a memory retrieval error wearing a different costume.
When a tool call fails or a prompt produces a wrong answer, the first question to ask is what memory read happened right before it, what got retrieved, from which layer, and when it was written, so the fault can be traced to its actual layer. Tracing a production run to find which architectural pattern broke, and at which point in the retrieval chain the error happened, is what turns a vague diagnosis, something like "the memory design is flawed somewhere," into a specific one: fix the boundary between episodic and semantic memory for this particular class of query.
What the leading memory layer implementations do differently
Every implementation choice described above, flat vector retrieval, hierarchical working memory, governed enterprise context graphs, carries its own production risk, and that risk traces back to the same root decision: whether the system treats memory type and memory architecture as the same question or as two separate ones. Pattern 2's flat vector store buys the lowest latency in the field but gives up relational reasoning, so multi-hop questions that need more than one fact chained together tend to fail quietly. Pattern 3's hierarchical working memory holds a session together efficiently but was not built to carry anything past that session's end, so teams that lean on it for cross-session continuity are asking it to do a job its design never accounted for. Pattern 5's enterprise context layer buys the strongest accuracy and the clearest audit trail of the five, at the cost of real upfront investment in ontology and governance, a cost that only pays off once an organization actually needs that level of accountability.
None of these patterns fails because the underlying model is weak. Each one fails at the boundary where its specific design assumption stops matching what the live workload is actually asking of it, and that boundary is only visible in the trace, session over session, layer by layer.